DNA in Prokaryotic & Eukaryotic Cells
DNA is found in all living cells, but the way it is organised differs between prokaryotes and eukaryotes.
Prokaryotic DNA
What you need to know (from the AQA specification)
What you need to know (from the AQA specification)
In prokaryotic cells, DNA molecules are short, circular and not associated with proteins.
- DNA is found free in the cytoplasm (prokaryotes have no nucleus)
- DNA molecules are short and circular
- DNA is not associated with proteins (no histones)
- Like all DNA, it is double-stranded (a double helix); only its shape and packaging differ
- Prokaryotes may also contain additional small, circular DNA molecules called plasmids
Eukaryotic DNA
What you need to know (from the AQA specification)
What you need to know (from the AQA specification)
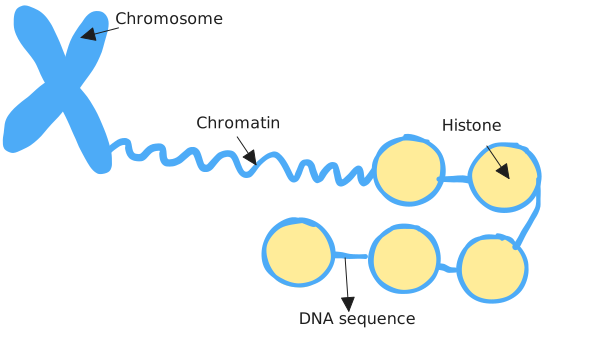
In the nucleus of eukaryotic cells, DNA molecules are very long, linear and associated with proteins, called histones. Together a DNA molecule and its associated proteins form a chromosome.
- DNA molecules are very long and linear
- DNA is associated with proteins called histones
- DNA wraps around histones, which helps to compact the DNA so it fits inside the nucleus
- Together, a DNA molecule and its associated histone proteins form a chromosome
Eukaryotic DNA (Organelles)
What you need to know (from the AQA specification)
What you need to know (from the AQA specification)
The mitochondria and chloroplasts of eukaryotic cells also contain DNA which, like the DNA of prokaryotes, is short, circular and not associated with protein.
- Mitochondria and chloroplasts also contain their own DNA. You might notice this when you look at the structures of Photosynthesis or Respiration
- This structure of the DNA is similar to prokaryotic DNA: short, circular and not associated with proteins
Tip
A common mistake is saying eukaryotic DNA is “circular”. Nuclear eukaryotic DNA is linear. The only circular DNA in eukaryotic cells is found in mitochondria and chloroplasts.
| Feature | Prokaryotic DNA | Eukaryotic (Nuclear) DNA | Eukaryotic (Organelle) DNA |
|---|---|---|---|
| Shape | Circular | Linear | Circular |
| Length | Short | Very long | Short |
| Associated with proteins | No | Yes (histones) | No |
| Location | Cytoplasm | Nucleus | Mitochondria / Chloroplasts |
Genes
What you need to know (from the AQA specification)
What you need to know (from the AQA specification)
A gene is a base sequence of DNA that codes for:
- the amino acid sequence of a polypeptide
- a functional RNA (including ribosomal RNA and tRNAs).
A gene occupies a fixed position, called a locus, on a particular DNA molecule.
Hopefully, you’ve understood how DNA is different between prokaryotic and eukaryotic cells and where it fits within the cell.
Now we take a specific segment of this DNA (as shown in the image below). This is a gene.
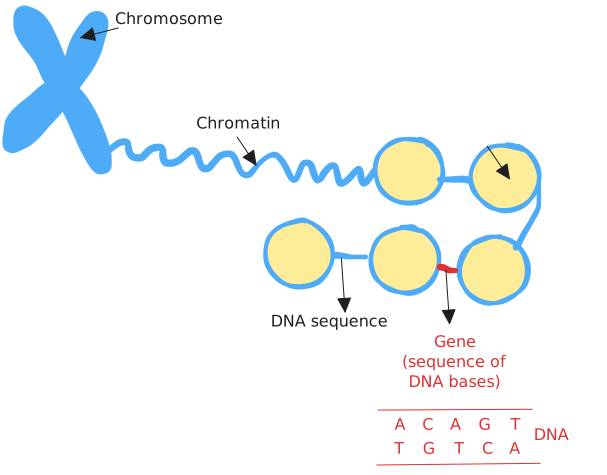
A gene is a sequence of DNA bases (nucleotides) that codes for either:
- The amino acid sequence of a polypeptide (a protein or part of a protein). Remember the sequence of amino acids in a polypeptide chain is called the Primary structure of a protein
- A functional RNA molecule, such as:
- tRNA (transfer RNA): used in translation to carry amino acids to the ribosome
- rRNA (ribosomal RNA): a structural and functional component of ribosomes
Locus (Gene’s Position)
Each gene occupies a specific, fixed position on a particular chromosome. This position is called a locus (plural: loci).
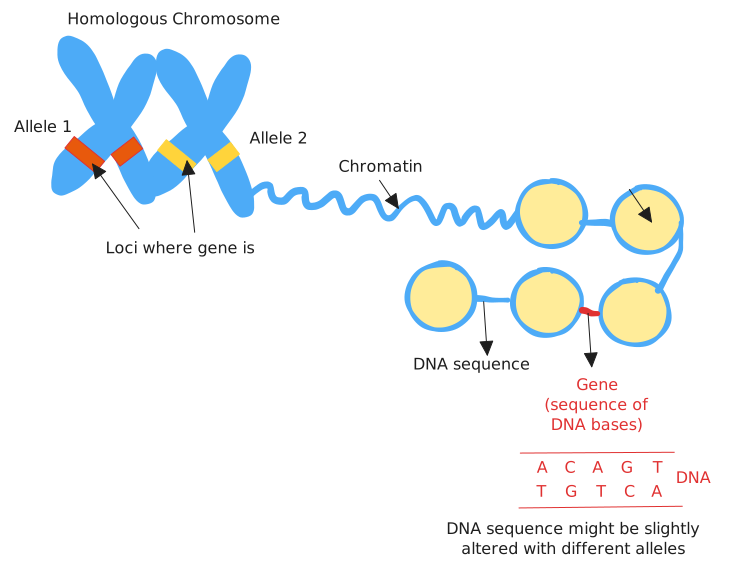
If you look at the image, you can see it’s showing 2 homologous chromosomes, each with 2 sister chromatids.
Why are there 2 chromatids not 1?
Why are there 2 chromatids not 1?
There are two chromatids because the DNA (in this image) has undergone replication. Each chromosome duplicates to form two identical sister chromatids joined at the centromere. If we looked before DNA replication, each homologous chromosome would consist of a single chromatid (one from each parent).
The gene is marked as allele 1 in the homologous chromosome on the left and allele 2 in the homologous chromosome on the right.
One allele might code for brown hair, and the other might code for blond hair. They are both the same gene, just different versions of it.
What is the difference between a gene and an allele?
What is the difference between a gene and an allele?
A gene is a sequence of bases that codes for a polypeptide or functional RNA. An allele is a different version of the same gene. Different alleles of a gene are found at the same locus on a chromosome, but have slightly different base sequences, which may result in a different amino acid sequence and therefore a different polypeptide/protein.
The Genetic Code
What you need to know (from the AQA specification)
What you need to know (from the AQA specification)
A sequence of three DNA bases, called a triplet, codes for a specific amino acid. The genetic code is universal, non-overlapping and degenerate.
The genetic code is the set of rules by which the base sequence of DNA is translated into a sequence of amino acids (a polypeptide).
Triplet Code
- A sequence of three DNA bases is called a triplet (or codon on mRNA)
- Each triplet codes for a specific amino acid
- Since there are 4 bases (A, T, C, G), there are 64 possible triplet combinations (4 x 4 x 4 = 64)
- There are only 20 amino acids, so some amino acids are coded for by more than one triplet codon. This is the idea of the degenerate nature of the genetic code. This is important in gene mutations, where even if there is a mutation in the DNA sequence, this might not cause a change in the sequence of amino acids (polypeptide chain)
Features of the Genetic Code
Key Features of the Genetic Code
- Universal: the same triplet codes for the same amino acid in all organisms
- Non-overlapping: each base is only part of one triplet; bases are read in consecutive, non-overlapping groups of three
- Degenerate: more than one triplet can code for the same amino acid
What does 'non-overlapping' mean?
What does 'non-overlapping' mean?
Each base in the DNA sequence is read only once and belongs to only one triplet. For example, in the sequence AATGCC:
- Non-overlapping reading: AAT | GCC (2 triplets)
- If it were overlapping: AAT, ATG, TGC, GCC (4 triplets)
The genetic code is non-overlapping, so the first reading is correct.
What does universal mean?
What does universal mean?
This means the same triplet codons code for the same amino acids in all species! So codon AUG codes for amino acid Met, in both bacteria and humans. This is important in recombinant DNA technology, as bacteria can use human DNA to produce human proteins
Why is the code described as 'degenerate'?
Why is the code described as 'degenerate'?
There are 64 possible triplet combinations but only 20 amino acids (plus stop codons). This means that most amino acids are coded for by more than one triplet. For example, the amino acid leucine is coded for by six different triplets. This is sometimes also called redundancy in the genetic code.
Non-Coding DNA
What you need to know (from the AQA specification)
What you need to know (from the AQA specification)
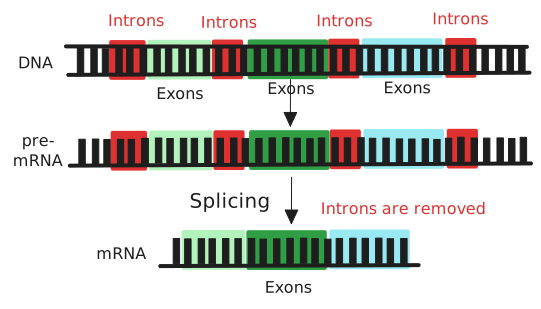
In eukaryotes, much of the nuclear DNA does not code for polypeptides. There are, for example, non-coding multiple repeats of base sequences between genes. Even within a gene only some sequences, called exons, code for amino acid sequences. Within the gene, these exons are separated by one or more non-coding sequences, called introns.
In eukaryotes, only a small proportion of nuclear DNA actually codes for polypeptides. The rest is non-coding DNA. This is one of the reasons why a mutation in the DNA sequence might not cause a change in the amino acid sequence. If a mutation is in the non-coding DNA region, it won’t change the amino acid sequence of the protein.
Exons & Introns
- Exons: sequences of bases within a gene that do code for amino acids
- Introns: sequences of bases within a gene that do not code for amino acids
- Exons and introns alternate within a gene
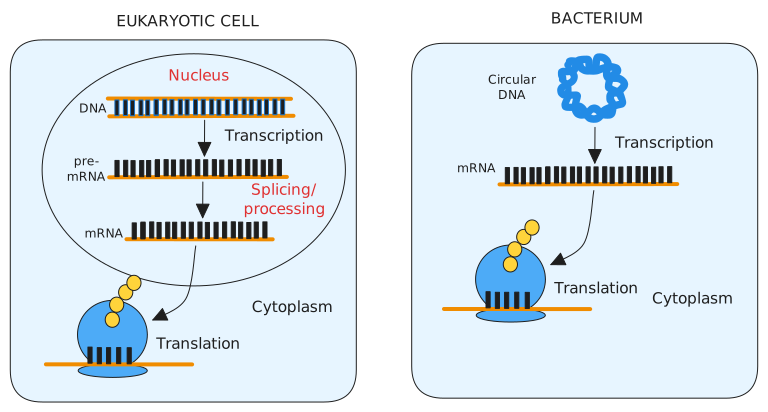
- During protein synthesis, introns are removed from the pre-mRNA after transcription, a process called splicing, forming mRNA. This ensures that only exons are translated into a polypeptide
Eukaryotic vs Prokaryotic
- Prokaryotic DNA often doesn’t contain these introns, so doesn’t undergo splicing like eukaryotic organisms
- This means that once a prokaryotic organism’s DNA is sequenced, it is easier to predict which proteins can be produced compared to eukaryotic organisms, as the initial DNA sequence in eukaryotes may contain introns. This comes up in Unit 8 determining the genome of simpler or more complex organisms
Non-Coding DNA Between Genes
- Much of eukaryotic DNA consists of sequences between genes that do not code for polypeptides
- These include multiple repeats of short base sequences
- These non-coding multiple repeats vary between individuals, which is the basis of DNA profiling / fingerprinting
Do prokaryotes have introns?
Do prokaryotes have introns?
Generally, no. Prokaryotic genes are mostly made up entirely of coding sequences (exons). Introns are a feature of eukaryotic genes. This is one of the differences between prokaryotic and eukaryotic gene structure.
What is the role of non-coding DNA?
What is the role of non-coding DNA?
Although non-coding DNA does not code for polypeptides, some of it has important regulatory functions. For example, some non-coding sequences can act as promoter regions that control when and how much a gene is expressed. However, much of non-coding DNA still has no known function.
How this topic is tested
This analysis is based on past paper data from 2017 to 2025. It is intended for interest only and is not predictive of what will appear in future papers.
- Tested in 4 of 9 years (2017–2025): 8 question parts worth 20 marks.
- 39th most-examined topic overall by marks, 6th in Unit 4.
Marks by year
Most-tested spec points
- DNA in Prokaryotes & Eukaryotes: tested in 4 parts (12 marks)
- The Triplet Code: tested in 2 parts (3 marks)
- Genes & Loci: tested in 1 part (3 marks)
- Exons, Introns & Non-coding DNA: tested in 1 part (2 marks)
Also links to: DNA Structure, Prokaryotic Cell Structure, Levels of Protein Structure.
Tips from examiner reports
What students commonly get wrong
- Prokaryotic DNA is still double-strandedWatch out: prokaryotic DNA is double-stranded (a double helix), just like eukaryotic DNA. It's not single-stranded, and it isn't all in plasmids. When asked how prokaryotic and eukaryotic DNA differ, describe the DNA itself (circular vs linear, histones or not, short vs long), not the cell (e.g. "prokaryotes have no nucleus"). 2018 P1 Q1.6 · 2020 P1 Q8.1
- Non-coding DNA isn't only intronsWatch out: non-coding DNA isn't just introns. There are also non-coding multiple repeats between genes. 2020 P1 Q8.2
- "Degenerate": triplets code for amino acidsWhen explaining "degenerate", say more than one triplet (codon) codes for the same amino acid. Talk about triplets or codons, not "bases", and say they code for amino acids, not "produce" them. 2018 P1 Q5.2
Exam Question Practice
Complete Table 1 to show three differences between DNA in the nucleus of an animal cell and DNA in a bacterial cell.
Table 1
| DNA in the nucleus of an animal cell | DNA in a bacterial cell | |
|---|---|---|
| 1 | ||
| 2 | ||
| 3 |
(3 marks)
Hint
Compare the two types of DNA: think about shape, length, associated proteins and non-coding sections.
Mark Scheme
Max 3 marks
Animal v bacterium
- (Associated with) histones/proteins v no histones/proteins (1 mark)
- Linear v circular (1 mark)
- No plasmids v plasmids (1 mark)
- Introns v no introns (1 mark)
- Long(er) v short(er) (1 mark)
Also accepted / rejected
Tips
- Compare the DNA itself, not the nucleus or the whole cell
- Write each pair directly opposite each other, e.g. linear v circular
- Bacterial DNA is double-stranded and forms a double helix, and it isn’t only found as plasmids
In the nucleus of a eukaryotic cell, DNA is found in chromosomes.
Describe the structure of a DNA molecule, and how DNA is arranged in a chromosome.
(6 marks)
Hint
Start with the monomer and how the monomers join. How are the two strands held together? Then: what is DNA wrapped around, and what does a chromosome look like before it divides?
Mark Scheme
Max 6 marks
DNA
- DNA is a polymer of nucleotides (1 mark)
- Each nucleotide has deoxyribose, a phosphate group and a nitrogenous base (1 mark)
- Nucleotides are joined by phosphodiester bonds (1 mark)
- Two strands form a double helix, held together by hydrogen bonds (1 mark)
- Adenine pairs with thymine, and cytosine pairs with guanine (1 mark)
Chromosome
- The DNA is associated with histones (proteins) (1 mark)
- When visible during cell division, a chromosome has two chromatids joined at a centromere (1 mark)
Also accepted / rejected
Also accepted
- “Polynucleotide” (point 1)
- A correctly labelled diagram
Not accepted
- Bases given as letters only (A, T, C, G) (point 5)
- “Adenosine” or “cysteine” for adenine or cytosine
Tips
- Start with DNA being a polymer of nucleotides; this is often left out
- Write the base names in full (adenine, thymine, cytosine, guanine); letters alone gain no marks
- Say where the phosphodiester bonds are: between nucleotides
- For the chromosome: DNA associated with histones, and two chromatids joined at a centromere
Table 1 shows some mRNA codons and the amino acid coded for by each codon. It also shows a property of the R group of each amino acid.
Table 1
| mRNA codon | Amino acid | Property of the R group |
|---|---|---|
| AAA | Lys | Positively charged |
| AAG | Lys | Positively charged |
| AUG | Met | No overall charge |
| GAC | Asp | Negatively charged |
| GAU | Asp | Negatively charged |
| GGA | Gly | No overall charge |
| GGC | Gly | No overall charge |
| GGU | Gly | No overall charge |
| UGG | Trp | No overall charge |
The genetic code is described as degenerate.
What is meant by this? Use an example from Table 1 to illustrate your answer.
(2 marks)
Hint
In Table 1, how many different codons give the same amino acid? Pick one amino acid and name its codons.
Mark Scheme
- More than one codon codes for a single amino acid (1 mark)
- Suitable example selected from Table 1 (1 mark)
For example, GGA, GGC and GGU all code for Gly
OR AAA and AAG both code for Lys
OR GAC and GAU both code for Asp
Also accepted / rejected
1. Accept ‘triplet’ or ‘sequence of 3 bases/nucleotides’ for ‘codon’.
1. Reject ‘production/produces’ for ‘codes for’.
Do not infer mp1 from mp2.
Tips
- Use the right terms: more than one codon (base triplet), not ‘base’, codes for an amino acid
- Codons ‘code for’ amino acids; they don’t ‘produce’ them
Scientists investigated mutations in the gene coding for a bacterial enzyme. Each mutation was a single base substitution.
The enzyme is a polypeptide 312 amino acids long.
What is the minimum number of bases in the gene coding for this polypeptide?
Answer = ________
(1 marks)
Hint
How many bases code for one amino acid?
Mark Scheme
936 (1 mark)
Also accepted / rejected
Accept 939 and 942 (for those that include start and/or stop codons)
Allow 1872 or 1878 or 1884
Ignore ‘bases/base pairs/bp/bps’ written after the numerical answer.
Tips
What earns marks
- 312 amino acids × 3 bases = 936
- Adding three or six bases for a start and/or stop codon is also credited, as is doubling the number because a gene is double-stranded DNA
Alternatives must be written directly opposite one another.
Do not award if only half of a mark point is written.
2 and 3. Do not credit if suggestion that bacterial DNA only exists as plasmids.
Reference to bacterial DNA being single stranded = max 2.
Reference to bacterial DNA not being helical = max 2.